Teks penuh artikel ini dalam bahasa Inggeris.
A website can appear healthy in a hosting dashboard while customers are seeing a timeout, a broken checkout page, or an expired SSL warning. That gap is why the best uptime monitoring tools matter: they test your site from outside your infrastructure and tell the right person when a real visitor may be unable to reach it.
For a small business or agency, monitoring should not create another system that needs constant attention. The right service gives you meaningful alerts, a clear incident history, and enough check types to catch problems before a customer reports them. It should also fit the way your team works, whether you manage one WordPress site or a portfolio of client domains and cloud applications.
What to Look for in the Best Uptime Monitoring Tools
An uptime check is often a simple request to a URL at a set interval. If the monitor cannot reach the page, it retries from another location before sending an alert. That is the baseline, but it is not the whole decision.
Check frequency affects how quickly you learn about an outage. One-minute monitoring is useful for revenue-generating sites, client portals, and applications with active users. Five-minute checks may be enough for a brochure site where a short interruption has lower business impact. Faster intervals typically cost more, so match them to the service rather than applying the same setting everywhere.
Alert routing is equally important. Email is a reasonable starting point, but an operational team may need SMS, phone calls, Slack, Microsoft Teams, or webhooks. Look for escalation rules that notify a second contact if the first person does not respond. Avoid sending every low-priority warning to every team member. Alert fatigue turns a useful signal into background noise.
Also consider what each monitor actually tests. HTTP and HTTPS checks confirm that a web page responds. Keyword checks can verify that a page contains expected content. Port checks help with mail servers, databases, and other network services. Transaction or browser checks go further by testing a login, form submission, shopping cart, or checkout path. A homepage can be available while the action that earns revenue is failing.
Finally, review the reporting and status-page options. Historical uptime reports are useful for client communication and internal reviews, but they should show planned maintenance separately from unexpected downtime. A public status page can reduce support tickets during an incident. For agencies, white-label reporting and grouped monitors can save considerable administrative time.
10 Best Uptime Monitoring Tools Compared
The tools below serve different operating models. A free plan may be the best starting point for a new business, while a larger team may need deeper observability, incident management, or browser-based transaction testing.
| Tool | Best for | Key strength | Consider before choosing | |---|---|---|---| | UptimeRobot | Simple website checks | Accessible setup and free entry tier | Advanced workflows require paid plans | | Better Uptime | Teams that need incident response | Strong alerting and on-call features | May exceed the needs of a single site | | StatusCake | Agencies and site portfolios | Broad test types and reporting | Plan limits need careful review | | Pingdom | Website performance visibility | Synthetic testing plus performance data | Can be costly for smaller portfolios | | Site24x7 | Businesses monitoring mixed infrastructure | Websites, servers, and applications in one product | Interface has more depth to configure | | Datadog | Technical teams with cloud workloads | Monitoring across infrastructure and services | Pricing and setup can grow quickly | | New Relic | Application-focused teams | Connects uptime data to app performance | Best value comes with broader adoption | | HetrixTools | Budget-conscious operators | Straightforward monitoring and blacklist checks | Fewer enterprise workflow options | | Freshping | Small teams starting with basic checks | Simple configuration and status pages | Feature depth is more limited | | Uptrends | Complex web journeys | Detailed browser and transaction monitoring | Best suited to higher-value use cases |
UptimeRobot
UptimeRobot is a practical choice when you need to monitor websites, APIs, ports, or keywords without a long setup process. Its simple monitor creation flow works well for business owners and freelancers who want to know whether a site is reachable. It also offers status pages and multiple notification options.
The trade-off is that teams with complex escalation policies, extensive analytics requirements, or many scripted transactions may eventually need more specialized capabilities. For core availability checks across a handful of sites, it is often a sensible place to begin.
Better Uptime
Better Uptime is designed around responding to incidents, not merely detecting them. It is a strong fit for teams that need on-call schedules, incident timelines, and escalations that move beyond email. Its approach is especially useful when several people share responsibility for a customer-facing application.
For a small marketing website, that level of incident workflow can be more than necessary. But if downtime needs a documented response process, Better Uptime can provide structure without building one from scratch.
StatusCake
StatusCake is a good option for agencies and businesses that want a broader mix of tests, including uptime checks, page speed monitoring, domain monitoring, and SSL certificate alerts. The domain and certificate checks are useful because outages are not always caused by hosting. An expired certificate or missed renewal can make a working site appear unavailable to visitors.
Review monitor allocations and interval limits before selecting a plan. Agencies should also test how easily they can organize client assets and produce the reports clients expect.
Pingdom
Pingdom is widely used for synthetic uptime monitoring and website performance testing. It can help separate a true availability failure from a slow page experience, which matters when a site technically loads but visitors leave before completing an action.
Its depth makes more sense for sites where speed and availability directly affect leads or sales. Smaller organizations should compare the cost of the features they will actually use rather than paying for performance analysis they rarely review.
Site24x7
Site24x7 suits organizations that need to monitor more than URLs. It covers websites, servers, networks, cloud resources, and applications, making it useful when a business runs a website alongside virtual servers, mail services, or internal systems.
The benefit is consolidation. The trade-off is configuration time. Set up a focused group of monitors first, then expand as your team establishes clear ownership for each alert.
Datadog
Datadog is a strong choice for technical teams operating cloud infrastructure, containers, APIs, and distributed services. Uptime monitoring becomes more useful when it can be viewed alongside logs, metrics, traces, and application behavior. That context can shorten troubleshooting when a failure is caused by a dependency rather than the website itself.
It is not the simplest or lowest-cost option for basic website checks. Teams should set budgets, tag services consistently, and understand pricing dimensions before expanding usage.
New Relic
New Relic is another option for teams that want to connect availability monitoring with application performance monitoring. It is particularly helpful when developers need to see whether an outage corresponds with slow database calls, deployment changes, or errors in a specific service.
For nontechnical website owners, the amount of data can feel excessive. It is a better fit where someone has clear responsibility for reviewing and acting on application-level information.
HetrixTools and Freshping
HetrixTools and Freshping are worth considering when affordability and basic operation are the priority. Both can cover the essential need to monitor availability and send notifications, and they are approachable for a small business managing a limited number of services.
Choose them when you want clear, focused monitoring rather than a full observability platform. If your requirements later include complex transactions, detailed incident workflows, or infrastructure metrics, you may need to add another tool or move to a more comprehensive service.
Uptrends
Uptrends is built for organizations that need detailed visibility into user-facing web experiences. Its browser monitoring and transaction checks can test workflows from multiple locations and browsers, making it useful for e-commerce sites, account portals, and business applications.
This is valuable when a simple HTTP 200 response is not enough. The cost and setup effort are easier to justify when a failed login, form, or checkout has a measurable business impact.
Set Up Monitoring That Produces Useful Alerts
Start by listing the services that customers and staff rely on: your main website, store checkout, client portal, API endpoint, email-related services, and key subdomains. Give each service an owner and a business priority. A contact form can wait longer than an online checkout, while an admin-only staging site may not need overnight paging at all.
For every public website, create an HTTPS monitor and an SSL certificate expiry alert. Add a keyword check for a key page if a generic error page could still return a successful response code. For stores and applications, add a transaction monitor that tests the actual path users take. Keep test accounts separate from real customer accounts, and avoid tests that create duplicate orders or form submissions.
Configure at least two notification paths for critical services. For example, send an immediate alert to the on-call contact and an escalation to a shared team channel if the incident remains open. Test alerts after setup. An alert that reaches an inactive mailbox is no better than no alert at all.
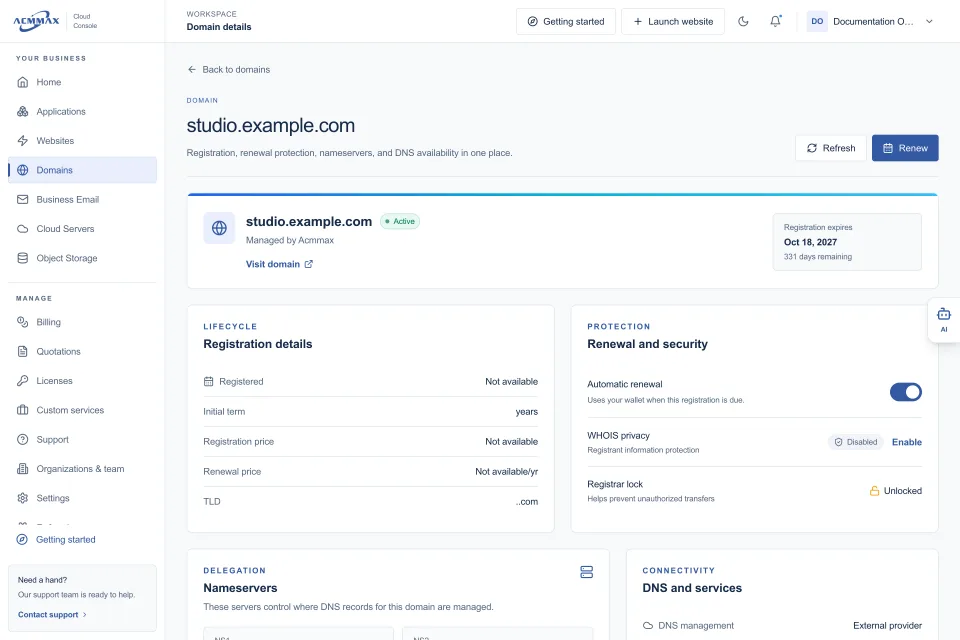
Monitoring does not replace good operations. Keep backups current, renew domains before expiry, review DNS changes carefully, and document where each service is managed. A central operations console such as ACMMAX can reduce the confusion of scattered hosting, domain, mail, and billing accounts, while independent uptime monitoring provides the outside-in view that confirms customers can still reach what you run.
Choose the tool that your team will configure properly and review consistently. A modest monitor with clear ownership is far more valuable than an advanced platform left with default alerts and no one accountable for the response.