Cloud VM Performance Review for Small Teams
A cloud VM performance review helps you measure CPU, memory, disk, and network limits, then choose the right server plan for business workloads today.
ACMMAX Insights ·
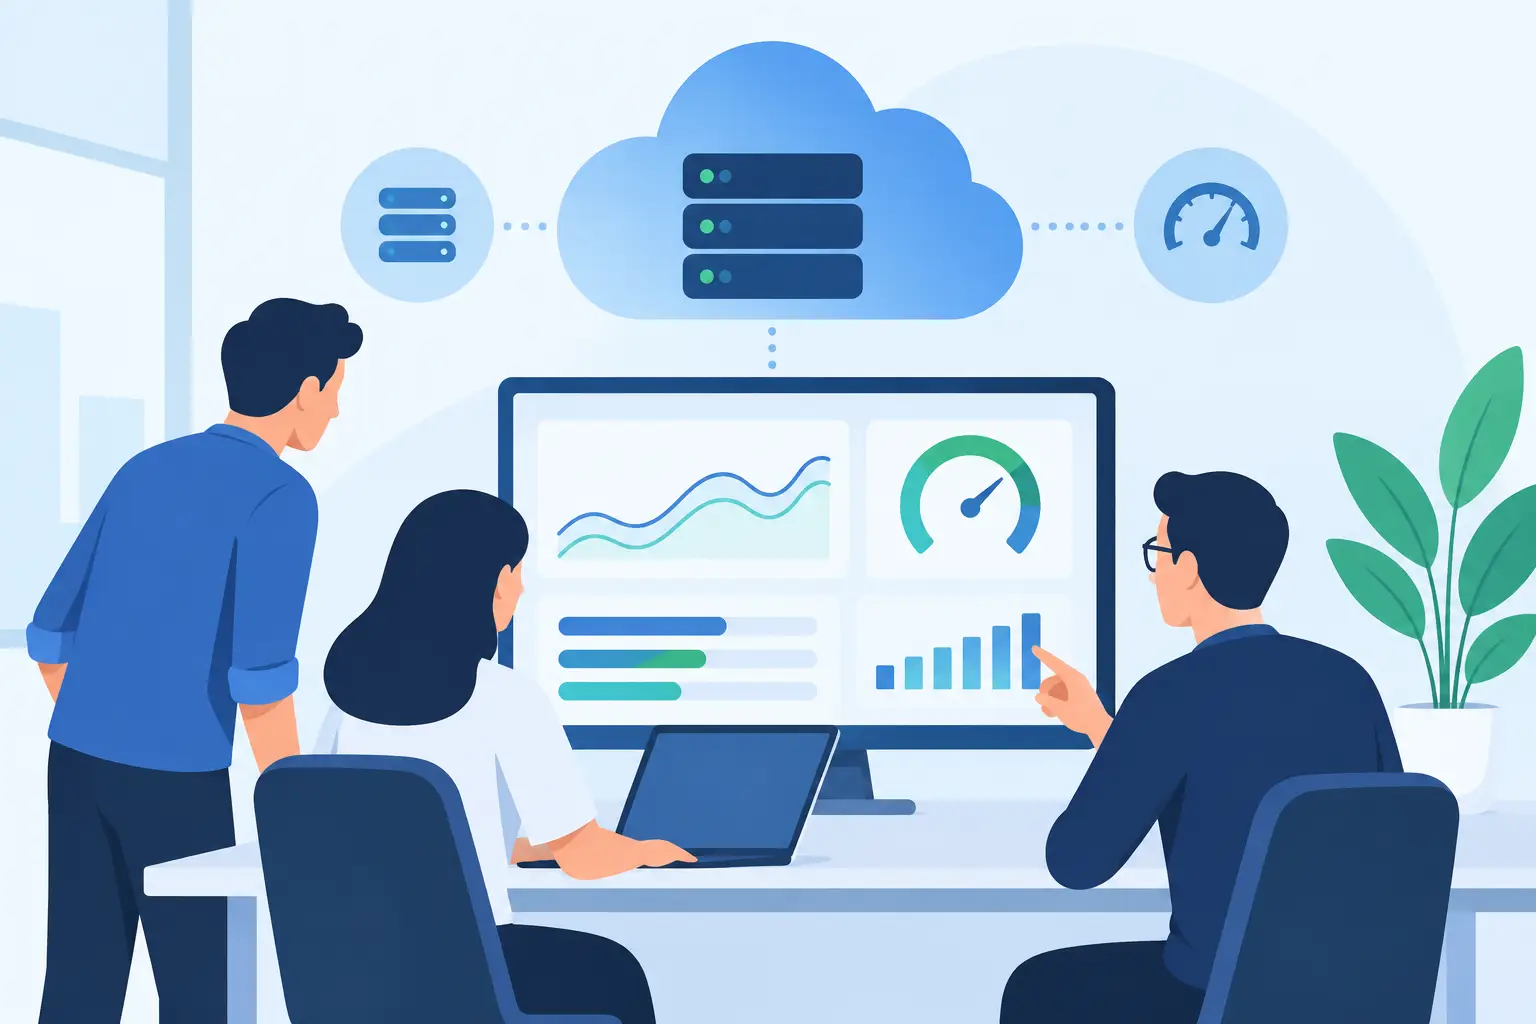
A slow checkout page, delayed client portal, or WordPress admin panel that stalls at busy hours is rarely solved by guessing. A cloud VM performance review gives your team a practical way to identify whether the server is short on CPU, memory, storage speed, network capacity, or simply configured for the wrong workload. The goal is not to buy the largest virtual machine available. It is to pay for the resources your applications can actually use and establish a clear point at which an upgrade is justified.
For small businesses, agencies, and technical teams, that review should connect infrastructure metrics to real outcomes: page response time, successful background jobs, reliable email processing, customer access, and predictable monthly costs.
What a cloud VM performance review should answer
A useful review answers a few operational questions. Can the VM handle normal demand without sustained resource pressure? Does it remain responsive during traffic spikes, backups, imports, deployments, or scheduled tasks? Is poor performance caused by the server itself, or by the application, database, DNS, external API, or network path?
Those distinctions matter. Adding more vCPUs will not fix an unoptimized WordPress plugin that runs expensive database queries on every page request. More memory will not solve a storage volume with high latency during a large database backup. A better server plan may be necessary, but it should follow evidence rather than frustration.
Review performance after launch, before a major campaign, after moving an application, and whenever users report a recurring pattern. For agencies managing multiple client sites, a regular review also prevents one growing project from quietly consuming the capacity needed by the rest of the portfolio.
Start with the workload, not the server size
A VM is only fast enough relative to the work it performs. Record what runs on the server before looking at graphs. A small brochure website, an active WooCommerce store, a staging environment, a database server, and an API application have very different resource profiles.
Consider normal traffic volume, peak concurrent users, average and peak request rates, scheduled jobs, file uploads, database size, cache behavior, and expected growth over the next six to twelve months. Also identify the events that create short but meaningful spikes. These often include marketing emails, ticket sales, product drops, nightly backups, report generation, bulk image processing, and software updates.
This context changes the interpretation of every metric. A VM showing 80% CPU for two minutes during a scheduled report may be operating normally. The same level for hours during customer activity may indicate that requests are queuing and users are waiting.
Define a baseline before making changes
Measure the environment during a normal business period and during the busiest period you can observe. Capture CPU use, memory use, disk latency and throughput, network traffic, application response time, database performance, and error rates. Keep the date, traffic level, recent code changes, and active services with the results.
A baseline is valuable because isolated numbers can be misleading. Ten percent CPU usage could be healthy, or it could hide a single-threaded application waiting on disk input. A response-time increase may come from an external payment service rather than the VM. Comparing metrics against known normal behavior makes anomalies easier to investigate.
Review the four VM resource areas
CPU: Look for sustained contention
CPU utilization shows how much processing capacity is being used, but averages alone are not enough. Watch for sustained high utilization during user-facing activity, rising load averages, long request queues, and increased response times that occur at the same time.
For web workloads, determine whether the application can use multiple cores. Some tasks scale well across vCPUs, while others are limited by a single process or database operation. If one core is repeatedly saturated while others are quiet, moving to a plan with more cores may produce little improvement. A VM with faster per-core performance, better application tuning, or a separate database service may be the more effective option.
Brief CPU peaks are not automatically a problem. The concern is sustained contention that prevents time-sensitive requests from completing promptly.
Memory: Treat swapping as an operational warning
Available memory is useful, but swap activity is often more revealing. When a VM regularly moves active data from RAM to disk, applications can become noticeably slow even if CPU usage appears reasonable. Database processes, PHP workers, Java applications, and caching layers can all compete for memory on a small server.
Check which processes consume memory and whether usage rises over time. A gradual increase can point to a memory leak, oversized caches, too many worker processes, or application behavior that needs attention. Increasing RAM may be appropriate, but first confirm that current allocations match the workload. Giving every service an aggressive memory limit can turn a manageable server into an unstable one.
Storage: Measure latency, not only capacity
Storage reviews often focus on free disk space, but performance depends heavily on input and output latency, IOPS, and throughput. A database can be slow even with plenty of unused capacity if the disk cannot keep up with frequent reads and writes.
Review latency during busy periods, especially when backups, log rotation, indexing, imports, or image processing run. Separate workloads where practical. For example, placing large backups in object storage instead of keeping them on the VM can protect local disk capacity and reduce unnecessary contention. Storage choices should also reflect recovery needs, retention policies, and how quickly files must be restored.
Do not wait until the disk is nearly full. Operating with limited free space can affect databases, temporary files, updates, and logging long before the volume reaches 100%.
Network: Separate bandwidth from response time
Network usage should be reviewed alongside application behavior. A VM may have adequate bandwidth but still deliver slow pages because of high latency to a database, overloaded upstream services, inefficient asset delivery, or excessive requests from bots.
Track inbound and outbound traffic, packet errors, connection counts, and application response times. If a public-facing site experiences sharp traffic bursts, use caching, a content delivery strategy, rate limiting, and application-level protections before assuming a larger VM is the only answer. These measures can reduce cost and improve reliability at the same time.
Connect server metrics to application performance
Infrastructure data is most useful when paired with what users experience. Track page-load and backend response times, uptime checks, failed transactions, 5xx errors, database slow queries, queue length, and job completion time. For WordPress, pay close attention to uncached page generation, PHP worker saturation, scheduled tasks, and plugin-driven database queries.
A practical test is to reproduce a known business action. Add items to a cart, submit a form, upload a file, run a report, or process an import while monitoring the VM. This provides stronger evidence than a generic benchmark because it reflects the application your customers actually use.
Load testing can help before a product launch or migration, but use it carefully. Test in a staging environment when possible, start with modest concurrency, and avoid creating artificial traffic that disrupts production users. A test should answer a business question, such as whether the store can handle a campaign forecast, rather than chase an impressive but irrelevant benchmark score.
Choose the next action based on the bottleneck
After the review, classify the result clearly. The VM may have adequate headroom, need configuration work, require an application fix, or need more resources. Avoid combining every possible change at once. If you upgrade the VM, add caching, change database settings, and deploy new code simultaneously, you will not know what solved the issue.
Use this decision guide:
| Finding | Likely next step |
|---|---|
| High CPU with slow requests and growing queues | Review application processes, then add CPU if the workload scales across cores. |
| Regular swapping or out-of-memory events | Reduce memory pressure, tune worker limits, or move to a VM with more RAM. |
| High disk latency during database activity | Review queries and backup timing; consider faster or separate storage. |
| Good VM metrics but slow user experience | Investigate application code, database queries, DNS, third-party services, and caching. |
| Short spikes only during predictable jobs | Reschedule work, throttle it, or use temporary capacity if available. |
Cost should remain part of the decision. A larger VM can be the right choice when it protects revenue, reduces support time, or prevents outages. However, ongoing overprovisioning is not efficient simply because it creates comforting utilization graphs. The best plan leaves reasonable headroom for normal variation while keeping routine operations affordable.
Make performance reviews part of routine operations
Set a simple review cadence: monthly for active production systems, after significant application changes, and ahead of events expected to increase traffic. Keep a short record of the VM plan, key metrics, incidents, actions taken, and results. This creates a decision history that is useful when team members change or clients ask why a server upgrade was recommended.
Centralized management also reduces the time spent gathering context. In a platform such as ACMMAX, teams can keep cloud services, domains, storage, billing, and support activity closer together, making it easier to connect a technical issue with the services around it.
A cloud VM performance review should leave you with one clear next step, whether that is tuning a database query, moving backups off the server, adjusting a worker limit, or selecting a larger plan. That clarity is what turns performance monitoring from another dashboard to check into a practical way to protect daily business operations.