Object Storage Versus Block Storage Explained
Object storage versus block storage explained for growing businesses: compare performance, cost, scalability, and the best use cases for each model.
ACMMAX Insights ·
A growing business can outgrow its storage setup without seeing it coming. Website backups multiply, customer uploads pile up, application databases need faster response times, and suddenly a low-cost storage decision starts affecting performance and operating costs. Understanding object storage versus block storage helps you choose the right foundation before storage becomes a bottleneck.
These two storage models solve different problems. Neither is automatically better. The right choice depends on what you are storing, how your applications access it, how quickly that data must respond, and how much operational complexity your team can support.
Object Storage Versus Block Storage at a Glance
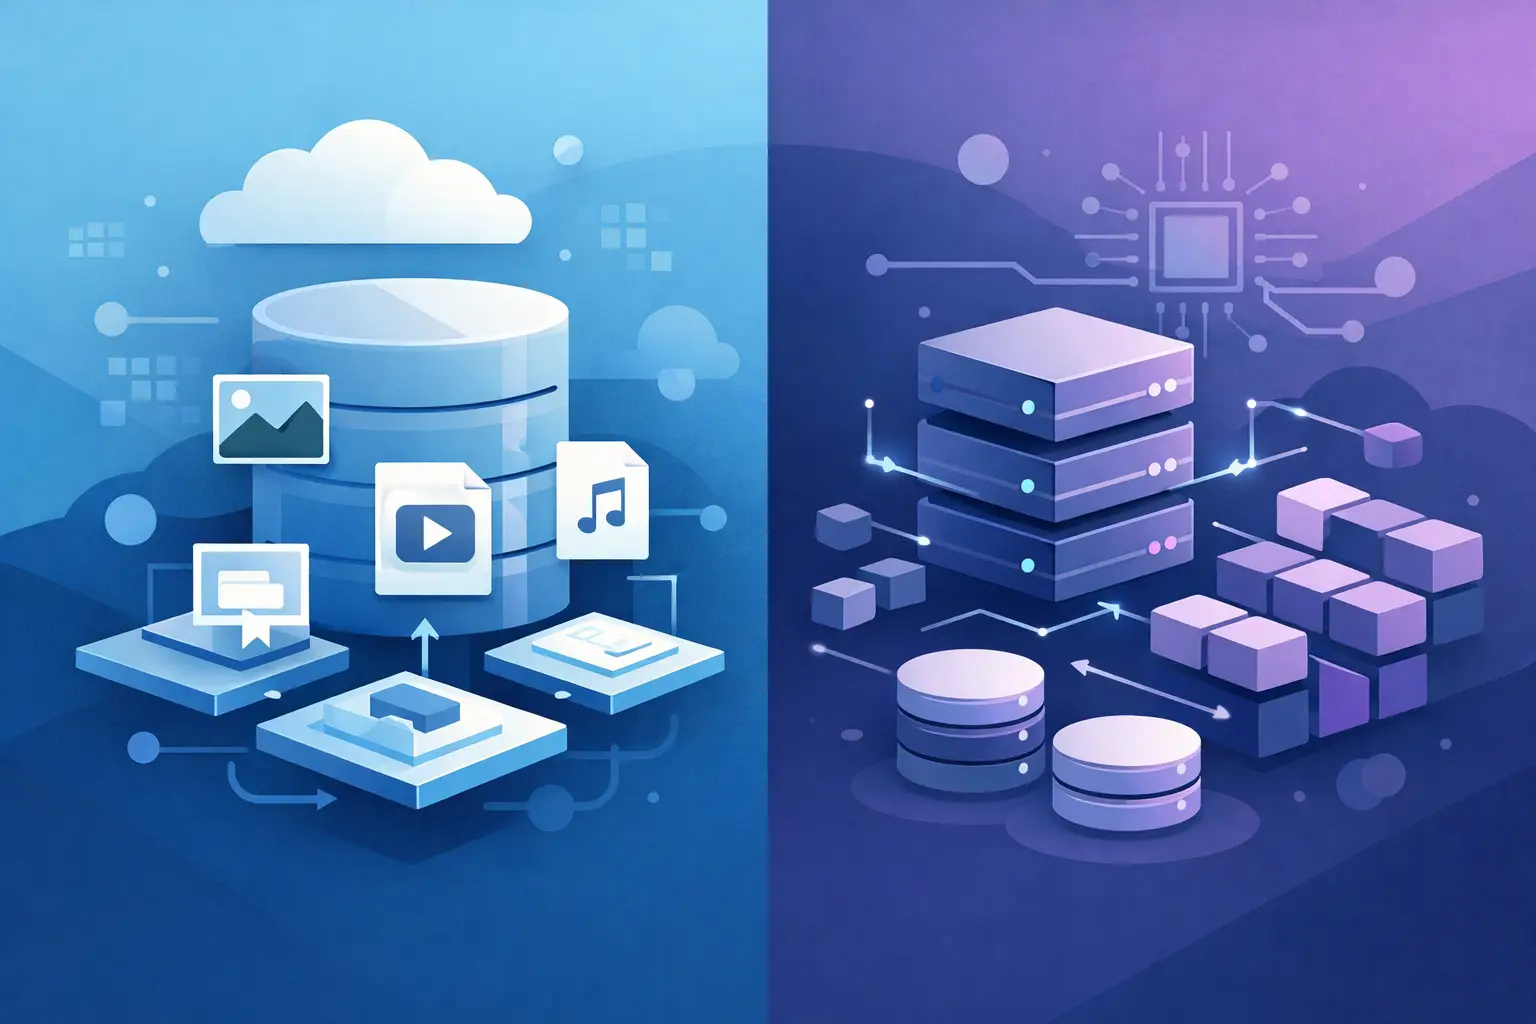
Object storage keeps data as complete, self-contained units called objects. Each object includes the file itself, a unique identifier, and metadata such as file type, creation date, owner, or retention rules. Instead of placing files inside a traditional folder hierarchy, object storage stores them in flat containers often called buckets.
Block storage divides data into fixed-size blocks and presents them to an operating system as a virtual disk. A cloud virtual machine, for example, can attach block storage and use it much like a physical SSD or hard drive. The operating system controls the file system, partitions, and how data is organized on that disk.
Here is the practical difference:
| Factor | Object Storage | Block Storage |
|---|---|---|
| Best for | Files, media, backups, archives, static assets | Databases, virtual machines, transactional apps |
| Access method | API or S3-compatible requests | Attached as a disk volume |
| Scalability | Built for very large, distributed data sets | Scales by adding or resizing volumes |
| Performance profile | High throughput, not usually lowest latency | Low latency and frequent read/write performance |
| Cost model | Typically cost-effective for large file collections | Usually costs more per GB for higher performance |
| Metadata | Rich, customizable metadata per object | Limited at the storage layer |
For an online operator, this often means object storage handles the files around your business, while block storage powers the workloads running the business.
How Object Storage Works for Business Files
Object storage is designed for scale, durability, and straightforward access over the internet. Your application sends a request for a specific object key, and the storage service returns that file. This model is ideal when files need to be stored reliably and accessed from websites, applications, backup tools, or distributed teams.
A product catalog full of high-resolution images is a strong object storage use case. So are video libraries, downloadable PDFs, WordPress media offloading, log archives, software releases, and customer-submitted documents. These files do not need to behave like a hard drive. They need affordable, scalable storage that can be accessed when required.
Metadata is one of the major advantages. A business can tag objects by client, project, region, content type, or retention period. That makes large collections easier to organize programmatically. Rather than relying only on folder structures, applications can search, manage, and automate data based on attributes attached to each file.
S3-compatible object storage is especially useful because it works with a broad ecosystem of backup applications, developer tools, content management workflows, and cloud-native software. ACMMAX object storage, powered by MinIO, is suited to businesses that want this familiar storage approach without adding another disconnected vendor to their stack.
Object storage does have limits. It is not intended to act as the main disk for a database server or a boot volume for a virtual machine. Applications that constantly modify small sections of a file may perform poorly if they are forced to retrieve and rewrite complete objects repeatedly.
Where Block Storage Delivers Better Performance
Block storage is built for workloads that need fast, predictable access to data. Because the server sees it as a disk volume, applications can use standard file systems and perform small, frequent reads and writes efficiently.
This matters most for databases. A MySQL, PostgreSQL, or Microsoft SQL Server database may process thousands of small transactions, update indexes, and write logs throughout the day. That workload needs low latency. Block storage is also the natural choice for operating system disks, virtual machine boot volumes, ecommerce application servers, and development environments where software expects a traditional disk.
For example, an agency might run a client portal on a cloud VM. The portal application, database, and operating system belong on block storage because they need responsive disk operations. The portal's uploaded project files, reports, image exports, and long-term backups can move to object storage, where capacity scales more economically.
Block storage is usually easier for traditional server administrators to understand because it follows familiar disk management patterns. You format the volume, mount it to the server, set permissions, and manage the file system. The trade-off is that you are responsible for more of the environment. Capacity planning, snapshots, backup schedules, and replication strategy require deliberate management.
Cost, Scale, and Management Trade-Offs
Price per GB is only one part of the decision. A cheaper storage option can become expensive if it slows down a revenue-producing application. Likewise, paying for high-performance disk storage to keep years of archived videos or backups wastes budget that could be used for marketing, development, or growth.
Object storage generally makes financial sense when your data volume can grow quickly and access patterns are less demanding. You can store massive collections without constantly provisioning additional disks or restructuring server file systems. It is a practical option for businesses with unpredictable file growth, especially those handling media, customer documents, or scheduled backups.
Block storage makes sense when speed and consistent input/output performance affect user experience or application reliability. The cost is justified when a slow disk can cause a checkout failure, delayed dashboard load, database lock, or service interruption.
Management differs as well. Object storage is API-first. It is easier to integrate into automated workflows, but some teams need time to adapt from drag-and-drop server folders to buckets, access keys, policies, and object paths. Block storage is familiar for server-based applications, but it requires active volume management and a clear recovery plan.
Security needs attention in both models. For object storage, use private buckets by default, restrict access with policies, rotate credentials, and avoid exposing customer files through publicly readable paths unless that is intentional. For block storage, control server access, encrypt volumes where available, keep operating systems patched, and maintain tested backups. Storage is only as secure as the access controls around it.
Choose Storage by Workload, Not Habit
The most efficient infrastructure setups use both models where they fit. Trying to force every file into a VM disk creates unnecessary storage pressure and makes scaling harder. Trying to run a high-transaction database from object storage creates avoidable performance problems.
Choose object storage when you need to store and distribute files at scale, including images, videos, backups, archives, static website assets, logs, and software packages. It is also a smart choice when multiple applications or users need controlled access to the same file collection without mounting a shared disk.
Choose block storage when an application needs a disk-like device with low-latency reads and writes. This includes server operating systems, databases, virtual machines, transactional web applications, and workloads that modify files frequently in small increments.
There are cases where the answer depends on architecture. A WordPress site may keep its database and core application files on block storage, then send media uploads to object storage. A backup platform may use block storage for its application server and object storage for the backup repository. A software company may use block storage for production databases while keeping release builds, user exports, and audit logs in object storage.
Build for the Next Stage of Growth
Storage decisions should support the business you expect to run six or twelve months from now, not just the website or application you have this week. If you expect growing file uploads, media libraries, backup retention, or customer-generated content, establish an object storage workflow early. If your revenue depends on an application database or virtual machine responding quickly, protect that workload with appropriately sized block storage.
The practical move is to map your data before you buy capacity. Separate active application data from durable file assets, estimate how often each data type is accessed, and identify which workloads would directly lose revenue if performance dropped. That simple exercise turns storage from a technical afterthought into a cost-controlled part of your growth plan.